 Sengol
sengol.authz.decision
allowed
#4,821
agent_id: kyc-triage-agent
tool: core_banking.read_account
prev 7c1e…a09f
Sengol sits in front of your production AI agents. It blocks unsafe tool calls and responses, scores every model call, gates every deploy, and writes each decision as a signed, tamper-evident record an examiner can check offline. It runs inside your own network. Governance says what should happen; Sengol proves what did.
The Overview shows the portfolio score against the ControlBook and which agents sit outside it, each with the signed record that backs it.
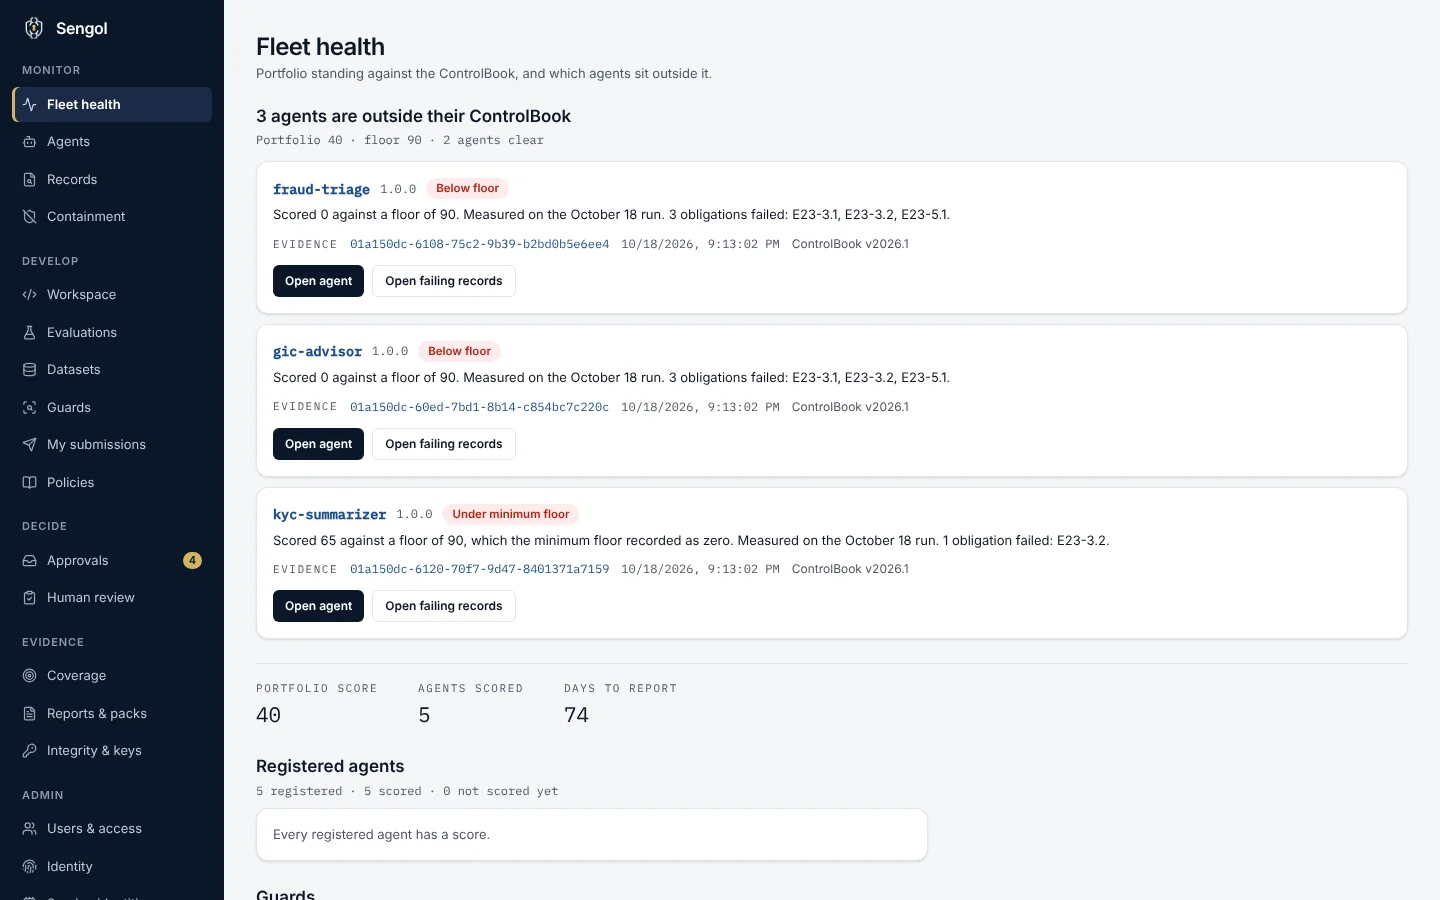
Screenshot of a Sengol demo install with sample data.
One request, then you choose: let us run your instance, or run it yourself. Nothing is held back in either path — every evaluator, every gate, every signed record.
A private Sengol instance on our AWS, pre-loaded with a reference agent and sample evidence so there is something to look at straight away.
Docker Compose, Helm or Terraform, or pip install sengol — with a 14-day licence file. No licence check or telemetry leaves your network, from the first request.
When an examiner asks "show me the evidence for this AI agent", a trace viewer is not an answer. Sengol produces the artifact that is: the gate verdict and the record you submit are one signed object.
Sengol is how you say yes to all three.
Every step is a Python call, a CLI command, an API route — and a signed record.
One call patches the Anthropic and OpenAI SDKs at class level. Every existing agent call is intercepted — no per-call changes. Or send OTel traces to the ingest endpoint, which records them without evaluating or blocking.
sengol.instrument()
Deterministic evaluators run first, and a CRITICAL failure skips the LLM judges. Otherwise the judges run concurrently — hallucination, PII, toxicity, tool misuse, adversarial robustness.
32 evaluators
Block the call inline before the user sees it, and block the deploy before it merges. The GitHub Action posts a verdict on the PR and exits non-zero on failure.
sengol gate
Each verdict is HMAC-signed and mapped to the obligation it satisfies; runtime verdicts are also hash-chained per agent. Export an evidence pack and hand it to an auditor — they check it with sengol-verify, a separate open-source tool with no dependency on Sengol and no licence to check.
sengol-verify
Runtime control, evaluation quality, cryptographic evidence, and access governance — designed as one chain, not four tools you integrate yourself.
Guardrails run inline in the request path. sengol.instrument() blocks the call on a failing CRITICAL pre-call evaluator and withholds the response on any failing post-call evaluator you configure. GuardrailRuntime acts on any failing evaluator by its mode: block and fallback withhold the response, retry returns it once retries run out. InlineEvaluator only scores; the CI gate fails the deploy, not the call.
import sengol

sengol.configure(
    agent_id="kyc-triage-agent",
    agent_version="2.4.0",
    policies=["OSFI_E23", "PIPEDA"],
)
sengol.instrument()   # every LLM call is now governed

# your existing code is unchanged
resp = client.messages.create(...)

# on a CRITICAL failure:
# BlockedError: PII_LEAKED — response withheld,
# signed AuditRecord #4,822 writtenDeterministic checks run first and short-circuit on CRITICAL, so you never pay for a judge call you don't need. LLM judges then fan out concurrently.
$ sengol gate --controlbook osfi_e23.yaml \
    --dataset-path suites/kyc.jsonl --fail-on-gate-failure

evaluating  128 cases · 11 evaluators
✓ PIIEvaluator                 128/128
✓ FaithfulnessJudge            126/128
✓ ToolCallMatch                128/128
✗ AdversarialRobustness        121/128

pass rate 0.943 < ControlBook pass_rate 0.95
GATE FAILED · exit 1 · deploy blocked
128 signed case records + 1 signed run record writtenEvery runtime decision is a signed, append-only audit record in a per-agent hash chain; CI gate verdicts are signed run records outside it. Change one byte in a chain and verification fails — loudly, and provably.
sengol-verify.$ sengol-verify pack.json
bundle kyc-triage-agent · 2026-Q2
records 4,823
chain OK every prev_hash links
hmac UNVERIFIABLE key material is not in the bundle
ed25519 OK countersignatures consistent
anchors OK 3 Merkle roots recomputed
no live server contacted · HMAC is checked online, against the storeSengol compiles a framework into obligations, routes each obligation to the evaluators that satisfy it, and keeps the evidence bound to the exact control that ran.
policy_id: OSFI_E23
mappings:
  - obligation: E23-3.3   # explainability
    evaluators: [ExplainabilityEvaluator]
    severity: HIGH
    coverage_required: true
    pass_rate: 0.95

  - obligation: E23-6.1   # ongoing monitoring
    evaluators: [DriftMonitorPresent]
    severity: CRITICAL
    coverage_required: true

# every record carries the obligation it satisfiedSengol enforces who may approve what, records it, and signs it.
$ sengol judge promote --record-id jmc_91f2 \
    --approver alice@bank.example

model card   verified  gate passed
TPR 0.94  TNR 0.92  κ 0.71  PC 0.88

checking segregation of duties…
  validate  actor bob@bank.example
  promote   actor alice@bank.example
  ✓ distinct actors · maker-checker satisfied

APPROVED · PromotionDecisionRecord signed
mfa_asserted=true · acr=urn:mace:...:mfaA GitHub Action runs your suite on every pull request, posts a comment with the verdict and coverage, and exits non-zero to block the merge. The gate verdict is the audit record — not a copy of it.
Escalation with SLAs, override authority by risk tier, and a versioned authority model whose status transitions are recorded. Who may reverse a governance action — and what evidence that takes — is written down and versioned.
Sengol is not OSFI-specific. It is opinionated about OSFI E-23 because that is where it ships first.
Adding a framework is one catalog.yaml entry — zero new Python classes.
Your internal model-risk standard works exactly the same way.
Sengol is an SDK first and a service second. The evidence chain is written to a store you own, in an environment you control. Nothing about the design requires your prompts or completions to reach us.
docker compose up
for a laptop. Helm and Terraform for AWS, Azure, GCP, OpenShift and on-prem.
Fully air-gapped, if that's the requirement.
Evidence is signed and written by the API you run into your own Postgres, append-only. Judges can run entirely on models inside your VPC.
Local HMAC or AWS KMS-backed signing with rotation, so old records still verify after a key change.
OIDC, SAML 2.0, SCIM 2.0, RBAC with a "you cannot grant what you don't hold" invariant, TOTP MFA, and audited break-glass.
The evidence API holds its state in Postgres and coordinates replicas through it. Three paths are single-replica: local-disk raw-trace capture, local key rotation and judge builds.
Tombstone erasure for data-subject requests. Erasure never breaks the chain.
AI agent governance is the practice of controlling what an AI agent is allowed to do at runtime, evaluating what it actually did, and producing a record that proves both. In practice that means four things working together: policies declaring which tools and actions an agent may use, guardrails enforcing them inline before a response reaches a user, evaluators scoring each interaction for failures like PII leakage or hallucination, and an audit trail an independent party can verify. Observability tools cover the third; governance requires all four.
Governance and assurance are not the same thing. Governance is the regime — the policies, the committees, who decides what an agent may do. Assurance is the evidence that the regime actually held: the testing, the verification and the record an independent party can check. In the three-lines model, governance is written in the first line and assurance is what the second and third lines — model validation and internal audit — are accountable for. Sengol is built for the assurance side: governance says what should happen, assurance proves what did.
Yes. OSFI Guideline E-23 on model risk management takes effect 1 May 2027 for federally regulated financial institutions in Canada, and extends to AI and machine-learning models. Sengol compiles E-23 into obligations, routes each one to the evaluators that satisfy it, and binds every signed record to the specific control that produced it — so coverage per agent and per period is a query, not a spreadsheet exercise. The same mechanism covers SR 11-7, the EU AI Act, FINTRAC, HIPAA and 24 other frameworks, and your own internal model-risk standard is one YAML entry.
An observability tool tells you what happened. Sengol decides what is allowed to happen, and produces evidence of the decision. It blocks a CRITICAL failure inline before the user sees it, blocks a failing deploy before it merges, and writes each verdict as a cryptographically signed record, runtime decisions in a per-agent hash chain, that a third party can check offline without access to your systems. The gate verdict and the record you hand an examiner are the same object, not two systems you reconcile.
Those are developer observability tools — they help engineers debug agents faster, and they do it well. They produce dashboards and scores. Sengol produces evidence: a signed record, hash-chained per agent for runtime decisions and checkable offline, bound to the specific obligation it satisfies, plus the runtime controls that decide what happens next.
Only where you point it. The SDK sends records over HTTP to the Sengol API you run, which signs them and writes them to your own Postgres; the SDK never connects to the database. Sengol itself sends no licence check or telemetry. Deploy with Docker Compose, Helm or Terraform inside your VPC, or fully air-gapped. If you use a hosted LLM judge, that provider sees the judge prompt, and any sink, exporter, timestamp-authority or identity-provider URL you set receives what it is sent; run a local judge model and set no external URLs, and nothing leaves your network.
Each audit record has a canonical payload signed with HMAC-SHA256 and linked to the previous record in a per-agent hash chain, so the store is append-only and tamper-evident; CI run records are signed but not chained. Records are countersigned with Ed25519 when a signing key is configured, and chain checkpoints are anchored to an RFC 3161 timestamp authority and Rekor when you set their URLs. A third party can check an exported bundle offline with sengol-verify, without access to your systems: chain linkage and Merkle roots from the bundle alone, and the Ed25519 countersignatures against a public key. The HMAC needs your key, so it is checked online against the store. Proving who signed means pinning a countersigning public key obtained out of band, which sengol audit verify --offline --trusted-key accepts.
Add it. A framework in Sengol is a catalog entry with obligations and evaluator routing — no new Python classes. That is exactly how internal bank policies and regional regimes are supported, and they get the same compiled obligations, the same signed evidence and the same reports as the 29 that ship in the box.
Runtime instrumentation is two lines at process startup — sengol.configure() and sengol.instrument() — with no per-call changes to your agent code. The CI gate is one workflow step. Mapping your controls into a ControlBook is the part that takes real thought, and it is the part that produces the evidence.
No. Sengol is proprietary software from version 2.0 and there is no free tier and no feature tiers: one licence unlocks the whole appliance — the SDK, every evaluator, the signed audit store, the Console, the CLI and CI gate, judge governance, ControlBook-driven reports, and the Docker Compose, Helm and Terraform installs, air-gapped or not. A 14-day pilot is the full product. The one exception runs the other way: sengol-verify, the offline verifier, is a separate Apache-2.0 tool that needs no licence at all.
Declare your controls once. Sengol makes them executable, verifiable, and defensible in production. A 14-day pilot, full capability, either way.